Precedence levels are dead; long live precedence sets

It was recently pointed out on lobste.rs that Zig has overhauled how its parser does operator precedence. The related documentation contains this cute little flowchart of the new operator precedence rules:

                     ┏━━━━━━━━━━━━━━━━━━━┓
                     ┃(expr)             ┃
                     ┃x() x[] x.y x.* x.?┃
                     ┃E!T                ┃
                     ┃x{}                ┃
                     ┃!x -x -%x ~x &x ?x ┃
                     ┗━━━━━━━━━▲━━━━━━━━━┛
          ┌─────────────┬──────┴───────┬───────┬──┬──┬─┐
          │             │              │       │  │  │ │
   ┏━━━━━━┷━━━━━┓╭Non╌Chaining╮ ╭Non╌Chaining╮┏┷┓┏┷┓┏┷┓│
   ┃* *% *| / ||┃╎      %     ╎ ╎ << <<|  >> ╎┃&┃┃^┃┃|┃│
   ┗━━━━━━▲━━━━━┛╰╌╌╌╌╌╌▲╌╌╌╌╌╯ ╰╌╌╌╌╌╌▲╌╌╌╌╌╯┗▲┛┗▲┛┗▲┛│
       ┏━━┷━━━━━━━━━━━━━┷━┓       ┌────┴───────┴──┴──┘ │
       ┃+ - +% -% +| -| ++┃       │                    │
       ┗━━━━━━━━━━━▲━━━━━━┛       │                    │
                  ╭┴╌Non-Chaining╌┴╮                   │
                  ╎== !=  < <= >= >╎                   │
                  ╰╌╌╌▲╌╌╌╌▲╌╌╌╌╌╌╌╯      ┌──────┬─────┘
                    ┏━┷━┓┏━┷━┓        ┏━━━┷━━┓┏━━┷━━┓
                    ┃and┃┃or ┃        ┃orelse┃┃catch┃
                    ┗━▲━┛┗━▲━┛        ┗━━━▲━━┛┗━━▲━━┛
                   ╭╌╌┴╌╌╌╌┴╌╌╌╌╌╌╌╌╌╌╌╌╌╌┴╌╌╌╌╌╌┴╌╮
                   ╎    Any expression location    ╎
                   ╰╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╯

If you're not familiar with Zig, some of these operators might be foreign to you. By removing some of the more exotic operators, and doing a few other tidy-ups, we get this flowchart:

                       ┏━━━━━━━━━━━━━━━┓
                       ┃(e) ident const┃
                       ┗━━━━━━━▲━━━━━━━┛
                ┏━━━━━━━━━━━━━━┷━━━━━━━━━━━━━━┓
                ┃x(e,…,e) x[e] x.ident x.* x.?┃
                ┗━━━━━━━━━━━━━━▲━━━━━━━━━━━━━━┛
                       ┏━━━━━━━┷━━━━━━━┓
                       ┃!x -x ~x &x ?x ┃
                       ┗━━━━━━━▲━━━━━━━┛
           ┌─────┬─────────────┴──┬────────┬────┬────┬──┐
           │     │                │        │    │    │  │
    ┏━━━━━━┷┓╭Non┴Chaining╮╭Non╌Chaining╮┏━┷━┓┏━┷━┓┏━┷━┓│
    ┃x*y x/y┃╎     x%y    ╎╎ x<<y  x>>y ╎┃x&y┃┃x^y┃┃x|y┃│
    ┗━━━━━━▲┛╰╌╌╌▲╌╌╌╌╌╌╌╌╯╰╌╌╌╌╌╌▲╌╌╌╌╌╯┗━▲━┛┗━▲━┛┗━▲━┛│
          ┏┷━━━━━┷┓              ┌┴────────┴────┴────┘  │
          ┃x+y x-y┃              │                      │
          ┗━━━▲━━━┛              │                      │
       ╭╌╌╌╌╌╌┴╌╌╌Non-Chaining╌╌╌┴╌╮                    │
       ╎x==y x!=y x<y x<=y x>=y x>y╎                    │
       ╰╌╌╌╌╌╌╌╌╌╌╌╌▲╌╌╌╌╌╌╌▲╌╌╌╌╌╌╯       ┌────────────┘
                ┏━━━┷━━━┓┏━━┷━━━┓     ┏━━━━┷━━━━━┓
                ┃x and y┃┃x or y┃     ┃x orelse y┃
                ┗━━━▲━━━┛┗━━▲━━━┛     ┗━━━━▲━━━━━┛
                ╭╌╌╌┴╌╌╌╌╌╌╌┴╌╌╌╌╌╌╌╌╌╌╌╌╌╌┴╌╌╌╌╌╮
                ╎    Any expression location     ╎
                ╰╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╯

I vastly prefer this presentation format over a table of operators which lists facts such as "addition has precedence level 5, exclusive-or has precedence level 7", but just in case it isn't clear, the meaning of this flowchart is:

If implementing a language, the question arises of how to translate this chart into a parser. There is plently of literature on how to translate precedence levels into a parser; see for example Pratt Parsing Index and Updates. If following the concrete exposition in Crafting Interpreters, we'd give each box in the flowchart a unique small integer, and end up with something like:

prec_primary    = 14 # (e) ident const
prec_call       = 13 # x(e,…,e) x[e] x.ident x.* x.?
prec_unary      = 12 # !x -x ~x &x ?x
prec_factor     = 11 # x*y x/y
prec_mod        = 10 # x%y
prec_shift      =  9 # x<<y x>>y
prec_bit_and    =  8 # x&y
prec_bit_xor    =  7 # x^y
prec_bit_or     =  6 # x|y
prec_term       =  5 # x+y x-y
prec_comparison =  4 # x==y x!=y x<y x<=y x>=y x>y
prec_and        =  3 # x and y
prec_or         =  2 # x or y
prec_orelse     =  1 # x orelse y
prec_none       =  0 # Any expression location

This approach works great for precedence levels, but the flowchart fundamentally cannot be represented using precedence levels. Instead, we need precedence sets:

prec_primary    = 0b100000000000000 # (e) ident const
prec_call       = 0b110000000000000 # x(e,…,e) x[e] x.ident x.* x.?
prec_unary      = 0b111000000000000 # !x -x ~x &x ?x
prec_factor     = 0b111100000000000 # x*y x/y
prec_mod        = 0b111010000000000 # x%y
prec_shift      = 0b111001000000000 # x<<y x>>y
prec_bit_and    = 0b111000100000000 # x&y
prec_bit_xor    = 0b111000010000000 # x^y
prec_bit_or     = 0b111000001000000 # x|y
prec_term       = 0b111110000100000 # x+y x-y
prec_comparison = 0b111111111110000 # x==y x!=y x<y x<=y x>=y x>y
prec_and        = 0b111111111111000 # x and y
prec_or         = 0b111111111110100 # x or y
prec_orelse     = 0b111000000000010 # x orelse y
prec_none       = 0b111111111111111 # Any expression location

If this looks to you like the reachability matrix of the flowchart, well done: it is exactly the reachability matrix of the flowchart.

Precedence levels can be manipulated in a parser using arithmetic operators: Crafting Interpreters contains precedence + 1 and precedence <= in key places. Precedence sets instead require bitwise tricks: isolate lowest set bit, clear lowest set bit, and bitwise and. Any level-based parser can be converted to a set-based parser by suitable replacement of arithmetic with these bitwise tricks, and I hope more languages follow Zig's lead here, freeing themselves from the tyranny of precedence levels and instead adopting precedence sets.
Using a lookup-table to correct an approximation

I often find myself writing (by which I mean generating) functions to convert enums to strings. A naïve implementation of such a function might look like:

const char* dxgi_format_to_string(unsigned x) {
  switch (x) {
  case  0: return "UNKNOWN";
  case  1: return "R32G32B32A32_TYPELESS";
  case  2: return "R32G32B32A32_FLOAT";
  case  3: return "R32G32B32A32_UINT";
  case  4: return "R32G32B32A32_SINT";
  case  5: return "R32G32B32_TYPELESS";
  case  6: return "R32G32B32_FLOAT";
  case  7: return "R32G32B32_UINT";
  case  8: return "R32G32B32_SINT";
  case  9: return "R16G16B16A16_TYPELESS";
  case 10: return "R16G16B16A16_FLOAT";
  case 11: return "R16G16B16A16_UNORM";
  case 12: return "R16G16B16A16_UINT";
  case 13: return "R16G16B16A16_SNORM";
  case 14: return "R16G16B16A16_SINT";
  case 15: return "R32G32_TYPELESS";
  case 16: return "R32G32_FLOAT";
  case 17: return "R32G32_UINT";
  case 18: return "R32G32_SINT";
  case 19: return "R32G8X24_TYPELESS";
  case 20: return "D32_FLOAT_S8X24_UINT";
  case 21: return "R32_FLOAT_X8X24_TYPELESS";
  case 22: return "X32_TYPELESS_G8X24_UINT";
  default: return NULL;
  }
}

Compiling the above with a modern gcc at -O0 or -O1 gives some fairly horrible assembly code. Thankfully, at -O2 and above, a modern gcc can rewrite it to something more along the lines of:

const char* dxgi_format_to_string(unsigned x) {
  static const char* const cases[] = {
    "UNKNOWN",
    "R32G32B32A32_TYPELESS",
    "R32G32B32A32_FLOAT",
    "R32G32B32A32_UINT",
    "R32G32B32A32_SINT",
    "R32G32B32_TYPELESS",
    "R32G32B32_FLOAT",
    "R32G32B32_UINT",
    "R32G32B32_SINT",
    "R16G16B16A16_TYPELESS",
    "R16G16B16A16_FLOAT",
    "R16G16B16A16_UNORM",
    "R16G16B16A16_UINT",
    "R16G16B16A16_SNORM",
    "R16G16B16A16_SINT",
    "R32G32_TYPELESS",
    "R32G32_FLOAT",
    "R32G32_UINT",
    "R32G32_SINT",
    "R32G8X24_TYPELESS",
    "D32_FLOAT_S8X24_UINT",
    "R32_FLOAT_X8X24_TYPELESS",
    "X32_TYPELESS_G8X24_UINT",
  };
  if (x > 22u) return NULL;
  return cases[x];
}

The assembly code for this is much nicer, although the table of pointers still takes up more space than I'd like (and that's before you account for each table entry needing a relocation entry...). It can be made smaller by concatenating all the strings together into a single contiguous piece of memory and then using a table of offsets into that memory, taking advantage of the fact that a relative offset can be much smaller than a pointer:

const char* dxgi_format_to_string(unsigned x) {
  const char* cases =
    /*  0*/ "UNKNOWN\0"
    /*  8*/ "R32G32B32A32_TYPELESS\0"
    /* 30*/ "R32G32B32A32_FLOAT\0"
    /* 49*/ "R32G32B32A32_UINT\0"
    /* 67*/ "R32G32B32A32_SINT\0"
    /* 85*/ "R32G32B32_TYPELESS\0"
    /*104*/ "R32G32B32_FLOAT\0"
    /*120*/ "R32G32B32_UINT\0"
    /*135*/ "R32G32B32_SINT\0"
    /*150*/ "R16G16B16A16_TYPELESS\0"
    /*172*/ "R16G16B16A16_FLOAT\0"
    /*191*/ "R16G16B16A16_UNORM\0"
    /*210*/ "R16G16B16A16_UINT\0"
    /*228*/ "R16G16B16A16_SNORM\0"
    /*247*/ "R16G16B16A16_SINT\0"
    /*265*/ "R32G32_TYPELESS\0"
    /*281*/ "R32G32_FLOAT\0"
    /*294*/ "R32G32_UINT\0"
    /*306*/ "R32G32_SINT\0"
    /*318*/ "R32G8X24_TYPELESS\0"
    /*336*/ "D32_FLOAT_S8X24_UINT\0"
    /*357*/ "R32_FLOAT_X8X24_TYPELESS\0"
    /*382*/ "X32_TYPELESS_G8X24_UINT";
  static const uint16_t offsets[] = {
      0,
      8,
     30,
     49,
     67,
     85,
    104,
    120,
    135,
    150,
    172,
    191,
    210,
    228,
    247,
    265,
    281,
    294,
    306,
    318,
    336,
    357,
    382,
  };
  if (x > 22u) return NULL;
  return cases + offsets[x];
}

This is pretty good, but the offsets table can be made even smaller. Consider the function x ↦ offsets[x]: it maps 0 to 0 and 22 to 382, so one possible linear approximation of this could be x ↦ x * int(round(382.0 / 22.0)), also known as x ↦ x * 17. It is rarely the case that x * 17 exactly equals offsets[x], but the difference between x * 17 and offsets[x] happens to always end up being in the range [-9, +10]. As such, the offsets table can be replaced with x * 17 and a table of corrections, where the corrections table occupies less space than the original offsets table:

const char* dxgi_format_to_string(unsigned x) {
  const char* cases =
    /*  0*/ "UNKNOWN\0"
    /*  8*/ "R32G32B32A32_TYPELESS\0"
    /* 30*/ "R32G32B32A32_FLOAT\0"
    /* 49*/ "R32G32B32A32_UINT\0"
    /* 67*/ "R32G32B32A32_SINT\0"
    /* 85*/ "R32G32B32_TYPELESS\0"
    /*104*/ "R32G32B32_FLOAT\0"
    /*120*/ "R32G32B32_UINT\0"
    /*135*/ "R32G32B32_SINT\0"
    /*150*/ "R16G16B16A16_TYPELESS\0"
    /*172*/ "R16G16B16A16_FLOAT\0"
    /*191*/ "R16G16B16A16_UNORM\0"
    /*210*/ "R16G16B16A16_UINT\0"
    /*228*/ "R16G16B16A16_SNORM\0"
    /*247*/ "R16G16B16A16_SINT\0"
    /*265*/ "R32G32_TYPELESS\0"
    /*281*/ "R32G32_FLOAT\0"
    /*294*/ "R32G32_UINT\0"
    /*306*/ "R32G32_SINT\0"
    /*318*/ "R32G8X24_TYPELESS\0"
    /*336*/ "D32_FLOAT_S8X24_UINT\0"
    /*357*/ "R32_FLOAT_X8X24_TYPELESS\0"
    /*382*/ "X32_TYPELESS_G8X24_UINT";
  static const int8_t corrections[] = {
     0,
    -9,
    -4,
    -2,
    -1,
     0,
     2,
     1,
    -1,
    -3,
     2,
     4,
     6,
     7,
     9,
    10,
     9,
     5,
     0,
    -5,
    -4,
     0,
     8,
  };
  if (x > 22u) return NULL;
  return cases + ((long)(x * 17u) + corrections[x]);
}

There's a general pattern here: an exact function can be computed via a fast but incorrect approximation followed by a table of corrections, and doing so can be profitable if this allows a smaller table than other approaches would require. This is not a novel idea, but it still needs repeating from time to time, even if only to remind compiler developers that there are still optimisations they're missing.

Encoding vcmpps and vcmppd

The x86 / x86-64 instruction sets have many instructions for comparing IEEE754 floating-point numbers. Casey Muratori recently asked about two of them:

It would be great if someone from Intel would share the rationale behind the immediate bit pattern of the AVX CMP instructions (eg., vcmppd, vcmpps). I've stared at it many times and it just seems "pure banacakes", as Jeff would say.

I can attempt to explain the immediate bit pattern of vcmpps and vcmppd, but it makes most sense to start somewhere else: the comiss and ucomiss instructions. These instructions compare two floats (say A and B) and then set flags based on the result. IEE754 floats have the convenient property that exactly one of these four statements is true:

  1. A > B
  2. A == B
  3. A < B
  4. A is unordered with respect to B (i.e. at least one of them is a NaN)

That fourth case is a bit of a mouthful, so I'll write it as A unord B from here on. When comparing A and B, the comiss and ucomiss instructions determine which case applies, and set the CF and ZF flags accordingly:

A > BA == BA < BA unord B
CF set to:0011
ZF set to:0101

(These instructions also set PF, but always as PF = CF & ZF, so for our purposes it suffices to look at just CF and ZF.)

The difference between comiss and ucomiss is how "loud" they are with respect to quiet NaNs, where comiss is "signalling" and ucomiss is "quiet". Most people consider loudness to be an obscure corner of IEEE754, but it is a corner which most pieces of hardware implement, and it amounts to running this flow chart before the comparison instruction:

                                       ↓
                               ╔════════════════╗
                           Yes ║ Is any operand ║ No
            ┌───────────────── ║    an sNaN?    ║ ───┐
            │                  ╚════════════════╝    │
            │                                        ↓
            │                             ╔════════════════╗
            │                         Yes ║ Is any operand ║ No
            │                       ┌──── ║    a qNaN?     ║ ───┐
            │                       │     ╚════════════════╝    │
            │                       ↓                           │
            │                ╔══════════════════╗               │
            │     Signalling ║ What loudness is ║ Quiet         │
            │   ┌─────────── ║ the instruction? ║ ──────┐       │
            │   │            ╚══════════════════╝       │       │
            ↓   ↓                                       │       │
          ╔══════════════╗      ╔══════════════╗        │       │
      Yes ║ Is mxcsr.IM  ║ No   ║ Set mxcsr.IE ║        │       │
    ┌──── ║ set to zero? ║ ───→ ║    to one    ║ ─┐     │       │
    │     ╚══════════════╝      ╚══════════════╝  │     │       │
    ↓                                             ↓     ↓       ↓
╔═══════════╗                               ╔══════════════════════╗
║ Raise an  ║                               ║     Execute the      ║
║ exception ║                               ║ instruction normally ║
╚═══════════╝                               ╚══════════════════════╝

That's enough context about comiss and ucomiss, so onward to vcmpps and vcmppd. These instructions operate on multiple SIMD lanes, and hence they can't set flags. Instead they compute a one-bit result per SIMD lane (and then replicate that bit to all 32 or 64 positions within the lane), with a five-bit field within the instruction configuring how to reach that result. If b0 through b4 represent those five bits, a de-novo design might be something like:

  1. The loudness is "signalling" if b0 is set, and "quiet" otherwise.
  2. If A > B, the one-bit result is b1.
  3. If A == B, the one-bit result is b2.
  4. If A < B, the one-bit result is b3.
  5. If A unord B, the one-bit result is b4.

The actual encoding of vcmpps and vcmppd is ... nothing like that. The reality is:

  1. The loudness is "signalling" if b4 ^ b1 ^ b0, and "quiet" otherwise.
  2. If A > B, the one-bit result is b2.
  3. If A == B, the one-bit result is b2 ^ !b0.
  4. If A < B, the one-bit result is b2 ^ b1 ^ b0.
  5. If A unord B, the one-bit result is b3 ^ b2 ^ (b1 & b0).

If it isn't immediately obvious that this encoding scheme covers every possibility exactly once, the entire five bits can be determined by:

  1. Decide what result you want when A > B, set b2 to this.
  2. Set b0 such that b2 ^ !b0 is the result you want when A == B.
  3. Set b1 such that b2 ^ b1 ^ b0 is the result you want when A < B.
  4. Set b3 such that b3 ^ b2 ^ (b1 & b0) is the result you want when A unord B.
  5. Set b4 such that b4 ^ b1 ^ b0 is the desired loudness.

In practice, nobody follows that process to determine the five bits. Instead, they just look up the combination they want from the table of cases:

b4,⋯,0NameA > BA == BA < BA unord BLoudness
0b00000vcmpeqps0100Quiet
0b00001vcmpltps0010Signalling
0b00010vcmpleps0110Signalling
0b00011vcmpunordps0001Quiet
0b00100vcmpneqps1011Quiet
0b00101vcmpnltps1101Signalling
0b00110vcmpnleps1001Signalling
0b00111vcmpordps1110Quiet
0b01000vcmpeq_uqps0101Quiet
0b01001vcmpngeps0011Signalling
0b01010vcmpngtps0111Signalling
0b01011vcmpfalseps0000Quiet
0b01100vcmpneq_oqps1010Quiet
0b01101vcmpgeps1100Signalling
0b01110vcmpgtps1000Signalling
0b01111vcmptrueps1111Quiet
0b10000vcmpeq_osps0100Signalling
0b10001vcmplt_oqps0010Quiet
0b10010vcmple_oqps0110Quiet
0b10011vcmpunord_sps0001Signalling
0b10100vcmpneq_usps1011Signalling
0b10101vcmpnlt_uqps1101Quiet
0b10110vcmpnle_uqps1001Quiet
0b10111vcmpord_sps1110Signalling
0b11000vcmpeq_usps0101Signalling
0b11001vcmpnge_uqps0011Quiet
0b11010vcmpngt_uqps0111Quiet
0b11011vcmpfalse_osps0000Signalling
0b11100vcmpneq_osps1010Signalling
0b11101vcmpge_oqps1100Quiet
0b11110vcmpgt_oqps1000Quiet
0b11111vcmptrue_usps1111Signalling

If this table and the exposition thus far looks like a convoluted mess (a.k.a. "pure banacakes"), it implies that we might be looking at the world from the wrong place. As with many x86 things, part of the perspective is history. In this case, the applicable question is: what if we didn't have five bits to play with, but instead only had two bits? Two bits allows four different cases, so the question can be re-framed as deciding which four cases you consider the most important. You can debate this, but the x86 designers made their choice, and it is the first four rows of the table:

b4,⋯,0NameA > BA == BA < BA unord BLoudness
0b00000vcmpeqps0100Quiet
0b00001vcmpltps0010Signalling
0b00010vcmpleps0110Signalling
0b00011vcmpunordps0001Quiet

It might look like A > B can't be computed using one of these four, but > and < are symmetric: A > B is the same as B < A, and < can be computed (albeit I'm ignoring that x86 often re-uses the left operand as the result register, and often allows the right operand to come from memory, both of which defeat symmetry).

Orthogonality is a desirable property in instruction sets, and in the context of comparisons it means that whenever you can test for X you should also be able to test for not X. This justifies adding a third bit (b2) which inverts all the results, thus giving us the first eight rows:

b4,⋯,0NameA > BA == BA < BA unord BLoudness
0b00000vcmpeqps0100Quiet
0b00001vcmpltps0010Signalling
0b00010vcmpleps0110Signalling
0b00011vcmpunordps0001Quiet
0b00100vcmpneqps1011Quiet
0b00101vcmpnltps1101Signalling
0b00110vcmpnleps1001Signalling
0b00111vcmpordps1110Quiet

This is where pre-AVX CPUs stopped, and for compatibility, cmpps (NB: no v) still stops here on post-AVX CPUs (I did say history was relevant). AVX came along and expanded three bits to five, but obviously the old and new behaviours should coincide when the new bits (b3 and b4) are both zero, as that's how you make the migration as easy as possible for software (i.e. for compilers, disassemblers, etc).

How do you plug in those two extra bits to get from these first eight cases to all 32 cases being covered? Perhaps you wire up one of them (b3) to flip the outcome of A unord B (and nothing else), and wire up the other (b4) to flip between Quiet ↔ Signalling. Doing so gets you exactly the full 32-entry table from earlier (ta da!).

That feels like a reasonable explanation of how vcmpps and vcmppd got to where they are, but how might a CPU actually implement them? Determining loudness from b4 ^ b1 ^ b0 feels reasonable enough, so the interesting question is how to compute the one-bit result. Given the presence of comiss and ucomiss, there could plausibly be a circuit which takes two floats and computes CF and ZF. In the case of comiss and ucomiss, those CF and ZF bits get wired into the flags register, whereas in the case of vcmpps there could be a circuit which takes those two bits along with b3 through b0 and computes the one-bit result. On a modern FPGA, this trivially maps to a single 6:1 LUT. On an ASIC, one cheap trick would be a 4:1 mux whose two control inputs are ZF and CF and four data inputs are b2, b2 ^ !b0, b2 ^ b1 ^ b0, and b3 ^ b2 ^ (b1 & b0). An alternative would be to rotate the mux to make b0 and b1 be the control inputs. If doing that, and ignoring b2 and b3 for a minute, this would require that the four data inputs be:

Mux control bits (b1,0)NameFormulas for mux data inputs
0b00vcmpeqps ZF & !CF
0b01vcmpltps CF & !ZF
0b10vcmpleps(CF & !ZF) | (ZF & !CF)
0b11vcmpunordps CF & ZF

An equivalent formulation is:

Mux control bits (b1,0)NameFormulas for mux data inputs
0b00vcmpeqps ZF & (ZF ^ CF)
0b01vcmpltps CF & (ZF ^ CF)
0b10vcmpleps(CF | ZF) & (ZF ^ CF)
0b11vcmpunordps CF & !(ZF ^ CF)

This equivalent formulation feels less intuitive, but the common (ZF ^ CF) term is neat. It also makes it easy to add in b3: in all four cases, the (ZF ^ CF) term just needs to be replaced by ((ZF ^ CF) | b3). Adding in b2 is also easy: conditionally negate the whole lot by having a ^ with b2 after the mux. Finally, if a mux feels like cheating, it can be expanded out to two-input logic gates to give:

tmp1 = (CF & (b0 | b1)) | (ZF & !b0)
tmp2 = ((ZF ^ CF) | b3) ^ (b0 & b1)
result = (tmp1 & tmp2) ^ b2
Are these forumulas elegant? No. Do they reveal some deep insight? Also no. But that's the life story of x86: it's a bit of a mess, justified by decades of history, and it gets the job done regardless.

A simplified model of Fil-C

I've seen lots of chatter about Fil-C recently, which pitches itself as a memory safe implementation of C/C++. You can read the gritty details of how this is achieved, but for people coming across it for the first time, I think there is value in showing a simplified version, as once you've understood the simplified version it becomes a smaller mental step to then understand the production-quality version.

The real Fil-C has a compiler pass which rewrites LLVM IR, whereas the simplified model is an automated rewrite of C/C++ source code: unsafe code is transformed into safe code. The first rewrite is that within every function, every local variable of pointer type gains an accompanying local variable of AllocationRecord* type, for example:

Original SourceAfter Fil-C Transform
void f() {
  T1* p1;
  T2* p2;
  uint64_t x;
  ...
void f() {
  T1* p1; AllocationRecord* p1ar = NULL;
  T2* p2; AllocationRecord* p2ar = NULL;
  uint64_t x;
  ...

Where AllocationRecord is something like:

struct AllocationRecord {
  char* visible_bytes;
  char* invisible_bytes;
  size_t length;
};

Trivial operations on local variables of pointer type are rewritten to also move around the AllocationRecord*:

Original SourceAfter Fil-C Transform
p1 = p2;p1 = p2, p1ar = p2ar;
p1 = p2 + 10;p1 = p2 + 10, p1ar = p2ar;
p1 = (T1*)x;p1 = (T1*)x, p1ar = NULL;
x = (uintptr_t)p1;x = (uintptr_t)p1;

When pointers are passed-to or returned-from functions, the code is rewritten to include the AllocationRecord* as well as the original pointer. Calls to particular standard library functions are additionally rewritten to call Fil-C versions of those functions. Putting this together, we get:

Original SourceAfter Fil-C Transform
  p1 = malloc(x);
  ...
  free(p1);
  {p1, p1ar} = filc_malloc(x);
  ...
  filc_free(p1, p1ar);

The (simplified) implementation of filc_malloc actually performs three distinct allocations rather than just the requested one:

void* filc_malloc(size_t length) {
  AllocationRecord* ar = malloc(sizeof(AllocationRecord));
  ar->visible_bytes = malloc(length);
  ar->invisible_bytes = calloc(length, 1);
  ar->length = length;
  return {ar->visible_bytes, ar};
}

When a pointer variable is dereferenced, the accompanying AllocationRecord* is used to perform bounds checks:

Original SourceAfter Fil-C Transform
  x = *p1;
  ...
  *p2 = x;
  assert(p1ar != NULL);
  uint64_t i = (char*)p1 - p1ar->visible_bytes;
  assert(i < p1ar->length);
  assert((p1ar->length - i) >= sizeof(*p1));
  x = *p1;
  ...
  assert(p2ar != NULL);
  uint64_t i = (char*)p2 - p2ar->visible_bytes;
  assert(i < p2ar->length);
  assert((p2ar->length - i) >= sizeof(*p2));
  *p2 = x;

Things become more interesting when the value being stored or loaded is itself a pointer. As already seen, local variables of pointer type have their accompanying AllocationRecord* variable inserted by the compiler, which the compiler can do because it has full control and visibility of all local variables. Once pointers exist in the heap rather than just in local variables, things become harder, but this is where invisible_bytes comes in: if there is a pointer at visible_bytes + i, then its accompanying AllocationRecord* is at invisible_bytes + i. In other words, invisible_bytes is an array with element type AllocationRecord*. To ensure sane access to this array, i must be a multiple of sizeof(AllocationRecord*). The extra logic for this is highlighted in green:

OriginalAfter Fil-C Transform
  p2 = *p1;
  ...
  *p1 = p2;
  assert(p1ar != NULL);
  uint64_t i = (char*)p1 - p1ar->visible_bytes;
  assert(i < p1ar->length);
  assert((p1ar->length - i) >= sizeof(*p1));
  assert((i % sizeof(AllocationRecord*)) == 0);
  p2 = *p1;
  p2ar = *(AllocationRecord**)(p1ar->invisible_bytes + i);
  ...
  assert(p1ar != NULL);
  uint64_t i = (char*)p1 - p1ar->visible_bytes;
  assert(i < p1ar->length);
  assert((p1ar->length - i) >= sizeof(*p1));
  assert((i % sizeof(AllocationRecord*)) == 0);
  *p1 = p2;
  *(AllocationRecord**)(p1ar->invisible_bytes + i) = p2ar;

One thing we've not yet seen is filc_free, which does something like:

void filc_free(void* p, AllocationRecord* par) {
  if (p != NULL) {
    assert(par != NULL);
    assert(p == par->visible_bytes);
    free(par->visible_bytes);
    free(par->invisible_bytes);
    par->visible_bytes = NULL;
    par->invisible_bytes = NULL;
    par->length = 0;
  }
}

The eagle-eyed will note that filc_malloc made three allocations, but filc_free only frees two of them: the AllocationRecord object isn't freed by filc_free. This gap gets covered by the addition of a garbage collector (GC). You heard that right - this is C/C++ with a GC. The production-quality Fil-C has a parallel concurrent incremental collector, but a stop-the-world collector suffices for a simple model. The collector traces through AllocationRecord objects, and frees any unreachable ones. It also does two more things:

  1. Upon freeing an unreachable AllocationRecord, call filc_free on it.
  2. If an AllocationRecord has length 0, any pointers to that AllocationRecord will be changed to point at a single canonical AllocationRecord with length 0.

Point 1 means that if you're using Fil-C, forgetting to call free is no longer a memory leak: the memory will be automatically freed by the GC. That isn't to say that calling free is useless, as it allows memory to be freed earlier than the GC might otherwise choose to. Point 2 means that after calling free on something, the accompanying AllocationRecord will eventually become unreachable, and thus itself eventually be freed.

Once a GC is present, it becomes tempting to use it more. One such use is making it safe to take the address of local variables, even if the resultant pointer is used after the local variable goes out of scope. If the compiler sees that a local variable has its address taken, and cannot prove that the address doesn't escape beyond the lifetime of the local variable, then the Fil-C transform will promote that local variable to be heap-allocated via malloc rather than stack-allocated. A matching free doesn't need to be inserted, as the GC will pick it up.

The final thing I want to highlight is the Fil-C version of memmove. This function from the C standard library manipulates arbitrary memory, and the compiler has no knowledge of what pointers might be present in that memory. To get past this problem, a reasonable heuristic is used: any pointers within arbitrary memory need to be completely within arbitrary memory, and need to be correctly aligned. This has the interesting consequence that memmove of eight aligned bytes behaves differently to eight separate 1-byte memmoves of the constituent bytes: the former will also memmove the corresponding range of invisible_bytes, whereas the latter will not.

That wraps up the simplified model. Some of the additional complications in the production-quality version include:

With the baseline understanding in place, I want to finish on a question: when might you want to use Fil-C? Personally, my answers are:

  1. You have a large quantity of C/C++ code which seems to work, but it hasn't been proven memory-safe, and you're willing to introduce a GC and take a large performance hit in exchange for memory safety (perhaps as a temporary measure until you rewrite in Java or Go or Rust).
  2. Just like you can run C/C++ code under ASan to find memory bugs, you can run it under Fil-C to find memory bugs.
  3. If you have a language with a strong compile-time story, and the compile-time language is the same as the runtime language (for example, Zig), you could use a Fil-C setup for safe compile-time evaluation, even if runtime evaluation is unsafe.
  4. Some people like to contemplate pointer provenance. If you've not come across this concept before, here's a nerd-snipe question: assuming p1 and p2 have the same type, is it valid for a compiler to rewrite if (p1 == p2) { f(p1); } to if (p1 == p2) { f(p2); }? In Fil-C, the answer is clearly "no", as it changes which AllocationRecord* gets passed along to f. This makes Fil-C a useful example of a concrete system which has pointer provenance.

Anthropics Compiler Challenge

Anthropic are currently in the tech news for (re)producing a C compiler using $20,000 of Claude's time, but I'm more interested in their compiler performance take-home challenge from two weeks ago. One part of Anthropic is showing that compiler engineers might be obsolete in the medium term, whereas another part is trying to find and hire the best compiler engineers on the planet. That both things can be simultaneously true is amusing to me, but perhaps not surprising: software engineers should be in the game of automating away their current problems so that they can move onward to new problems. Just as the higher education sector has expert lecturers teaching novice undergraduates, the AI sector can have expert humans teaching novice AIs.

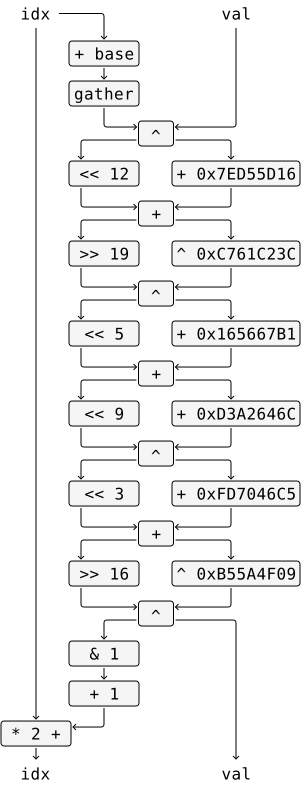
Anyway, enough philosophical musing, I want to look at that compiler take-home challenge. It revolves around this little computation graph:

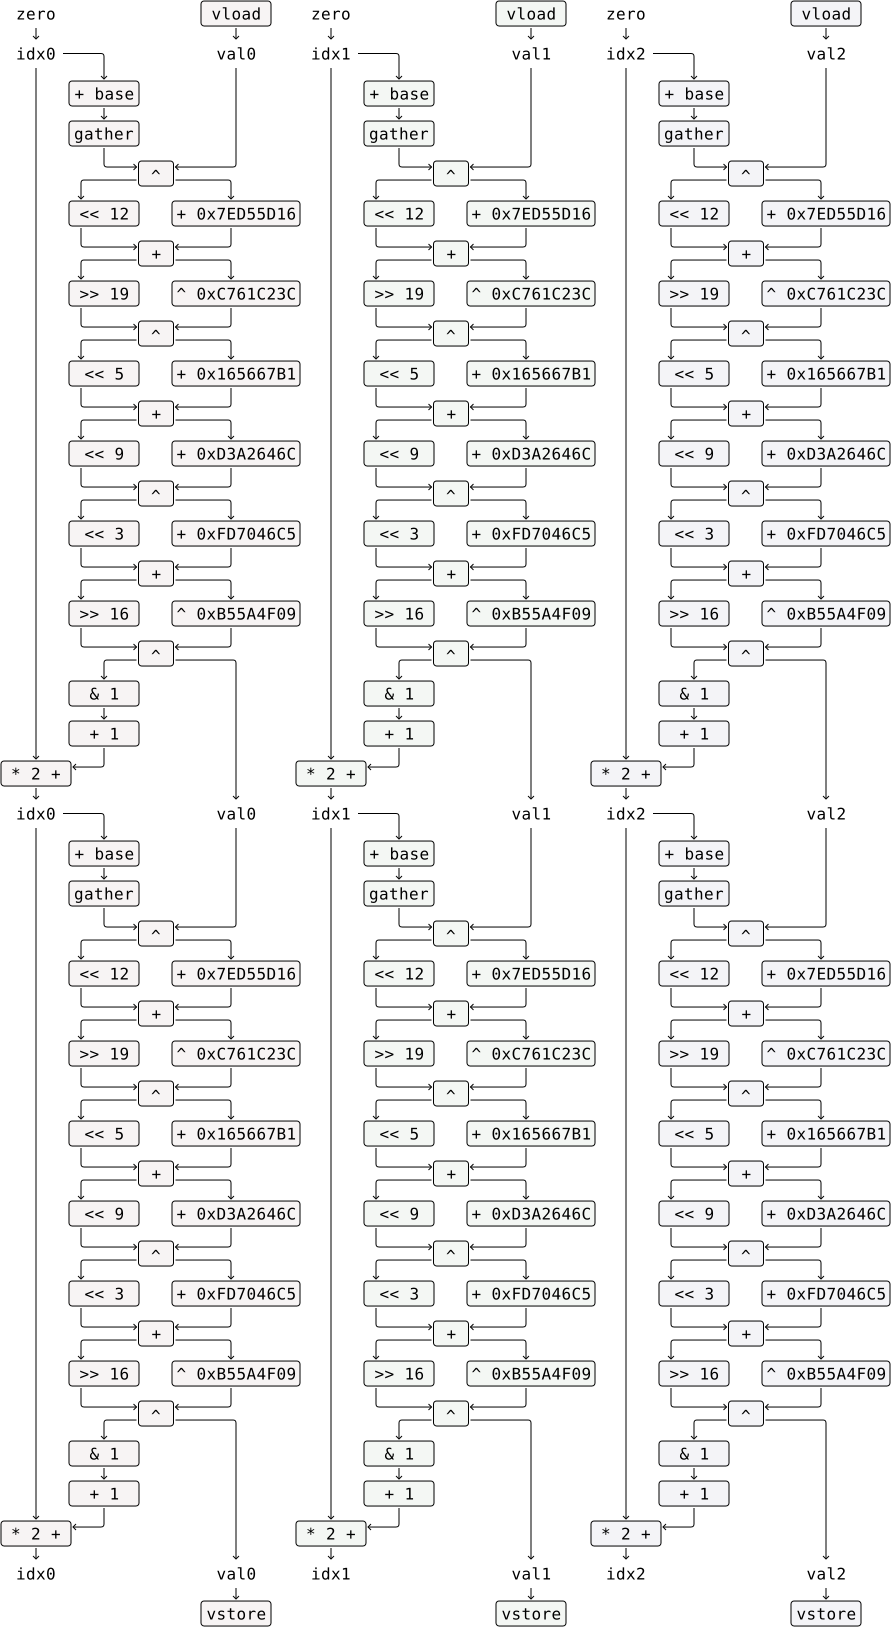
Several copies of this graph can be chained together vertically ("rounds"), and then multiple copies can be placed side-by-side horizontally ("batch size"). For example, here are two vertical copies and three horizontal copies, along with the initial loads and final stores:

The full challenge involves 16 vertical copies and 32 horizontal copies, meaning 512 copies in total. The challenge is to take this computational graph and schedule it on a hypothetical CPU capable of ~10 instructions per cycle, trying to minimise the total cycle count. For example, scheduling it in 1300 cycles involves considering a grid which is ~10 cells wide and 1300 cells tall, then placing each box from the diagram in one of those cells. Placing boxes into grid cells isn't all that hard, but I've been glossing over an important fact which makes it hard: the ~10 cells in each grid row are not all the same. Each grid row in fact consists of 7½ "valu" cells, 2 "load" cells, 2 "store" cells, and finally 1 "flow" cell. Most of the boxes from the diagram have to go into a "valu" cell, but there are a few exceptions:

What looked simple now looks a bit harder: the 512 total "gather" boxes require 4096 "load" cells, thus requiring a grid at least 2048 cells tall. At this point, if I told you it was possible to make everything fit into a grid less than 1000 cells tall, you might think I was delusional. I assure you it is possible though, courtesy of two main strategies:

  1. Reducing the number of boxes on the diagram.
  2. Replacing some of the "+ base" and "gather" boxes with alternatives.

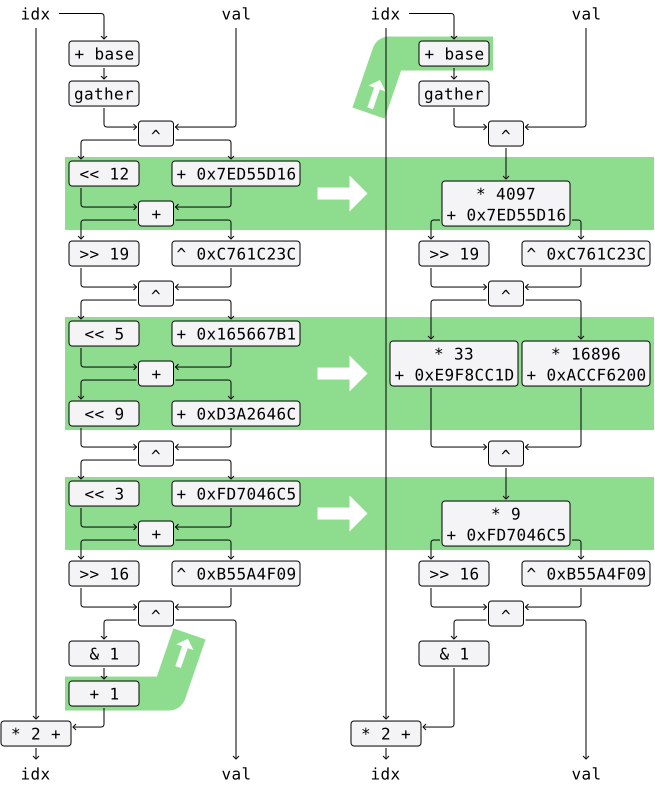
I don't have much to say about strategy one, as the majority of the changes can be shown using a single diagram:

Strategy two is more interesting. The gather operation can be replaced with a selection tree: preload the values of every possible idx, and use the output from all earlier & 1 boxes to select the appropriate value out of all the preloaded values. Each binary select operation requires either a single "flow" cell, or one or two "valu" cells. The number of binary select operations required to replace a "+ base" and "gather" then depends on the vertical level within the graph:

LevelGather-styleSelect-style (ignoring one-off overheads)
01x "valu" + 8x "load"Free
11x "valu" + 8x "load"1x ("flow" or "valu")
21x "valu" + 8x "load"2x ("flow" or "valu") + 1x ("flow" or 2x "valu")
31x "valu" + 8x "load"4x ("flow" or "valu") + 3x ("flow" or 2x "valu")
41x "valu" + 8x "load"8x ("flow" or "valu") + 7x ("flow" or 2x "valu")
51x "valu" + 8x "load"16x ("flow" or "valu") + 15x ("flow" or 2x "valu")
⋮⋮⋮

More than 280 gathers can be gainfully replaced with selection trees. Doing so massively reduces the number of "load" cells required, at the cost of increasing the number of "flow" cells required. In turn, some of those "flow" cells can be traded for "valu" cells. Part of the challenge is finding just the right instruction mix as to equally balance "valu" and "load" and "flow" in the 7½ : 2 : 1 ratio. If the full graph is considered as a whole, it isn't too hard to balance the overall instruction counts as to hit 7½ : 2 : 1. Unfortunately, this isn't enough: every single one of the ~1000 cycles wants to hit that 7½ : 2 : 1 ratio, which means instruction selection and instruction scheduling are intertwined problems. This is where the real meat of the challenge is found: the space of possible instruction selections and instruction schedules is vast, and so the winner is the person (or system) capable of finding the best point in that search space. If you can find a good point, submit it to the leaderboard (or email Anthropic asking for a job).

You might also ask whether this challenge is a reasonable proxy for actual compiler engineer experience. It is easy to cheat the default test harness, but I'm going to ignore that, as the objective is clearly to find compiler engineers rather than security engineers, and human review of submissions can easily identify the latter. There are also various well-known compiler problems which the challenge doesn't touch: there's no control flow, all instructions have single-cycle latency, memory hazards can be (almost) entirely ignored, there are no cache effects, and no doubt all sorts of other things. The target machine is clearly fictitious, but there is more VLIW hardware in the AI space than many people realise, and that final ½ "valu" slot is an endearing complication. Overall I think it is an OK proxy, though I much prefer it as an unlimited-time challenge rather than its original format of a two-hour timed exam.

page: 1 2 3